

This document introduces advanced configuration options for Web RUM SDK, helping you customize data collection behavior based on your business needs.
Protect Sensitive Data
Mask personally identifiable information and sensitive data
Associate User Sessions
Link user sessions with internal user identifiers
Reduce Data Volume
Lower RUM data collection through sampling
Enrich Context
Add rich contextual information to data
Override Default RUM View Names
Flashduty RUM automatically generates view events when users visit new pages or when URLs change in SPAs. View names are calculated from the current page URL by default, with variable IDs (path segments containing numbers) automatically removed. For example,/dashboard/1234 and /dashboard/9a are normalized to /dashboard/?.
You can manually track view events and specify custom names by setting the trackViewsManually option.
Configure Manual View Tracking
1
Enable Manual Tracking
Set
trackViewsManually to true during initialization:rum-init.js
2
Call startView Method
Call the
startView method on each new page or route change:string
View name, defaults to page URL path
string
Service name, defaults to the service specified when creating the RUM application
string
Application version, defaults to the version specified when creating the RUM application
object
Additional context for the view, applied to the view and its child events
React Router Integration
React Router v6 Example
React Router v6 Example
RumTracker.jsx
Set View Name
Use thesetViewName method to update the current view’s name without starting a new view:
Control Initial View Web Vitals Collection
The Web SDK collects Web Vitals and initial view performance metrics by default, including FCP, LCP, FID, and loading time. These metrics use the page navigation start time as their baseline, which works for pages that real users open directly. If your page loads before it becomes visible to the user, such as when it is prerendered by the browser, opened in a background tab, or initialized early by a host container, initial view metrics can be calculated from an unrelated navigation start time. This can make FCP, LCP, or loading time look abnormally high. SettrackWebVitals to false during initialization to disable only Web Vitals and initial view performance metrics on the initial load view.
rum-init.js
trackWebVitals only affects Web Vitals and initial view performance metrics on the initial load view. Resource, long task, user action, error, and later view events continue to be collected according to their own configuration options.Enrich and Control RUM Data
Using thebeforeSend callback function, you can intercept and modify events before they are sent to Flashduty:
- Enrich events: Add additional context attributes
- Modify events: Change event content or mask sensitive information
- Discard events: Selectively discard specific RUM events
Context Types
Different event types correspond to different contexts:Enrich RUM Events
Add context attributes to events, such as adding response header data to resource events:Modify RUM Event Content
For example, mask email addresses from view URLs:Modifiable Attributes
Discard RUM Events
Returnfalse in beforeSend to discard specific RUM events:
User Sessions
By adding user information to RUM sessions, you can:- Track specific user browsing paths
- Understand which users are most affected by errors
- Monitor performance for key users
User Attributes
The following are optional user attributes; we recommend providing at least one:string
Unique user identifier
string
User-friendly name, displayed by default in RUM UI
string
User email, displayed if no name is provided
User Session API
- Set User
- Get User
- Update Property
- Remove Property
- Clear User
After user session information changes, subsequent RUM events will contain the updated information. After logout (calling
clearUser), the last view still retains user information, but subsequent views and session-level data will not.Sampling
By default, Flashduty RUM collects data from all sessions. You can set the sampling rate via thesessionSampleRate parameter to reduce the number of collected sessions:
On-error session capture
Web SDK 0.3.0 and later can capture sessions and replays that report an error in addition to ordinary sampling. Both options are booleans, default tofalse, and apply only to sessions not selected by the corresponding sample rate. Sessions already selected keep their normal collection behavior.
For example, keep 20% of ordinary sessions and capture error sessions and their replays from the remainder:
- Buffer first, upload on error: sessions missed by ordinary sampling collect into memory from the start and retain a limited history. The first qualifying error releases that history. The lookback is at most one minute, not a guaranteed full minute, and cannot recover data from before SDK initialization or recording started.
- No error means no storage or charge: if a session retained by
sessionOnErrornever reports an error, neither its events nor its replay are uploaded, and it incurs no session charge. With onlysessionReplayOnErrorenabled, candidate replays without errors are not uploaded or charged, but RUM sessions selected by ordinary sampling are still uploaded and billed normally. - Each captured session counts once: ordinary sampling and on-error capture do not count the same session twice. On-error sessions count as actual sessions in statistics, without extrapolation by
1 / sessionSampleRate, and repeated errors do not count them again. - A RUM error event triggers capture: examples include automatically captured JavaScript errors and errors reported with
addError(). Errors discarded bybeforeSendor rate limiting, and the SDK’s own errors, do not trigger capture. A failed request or HTTP 5xx resource event alone does not trigger capture.
At
sessionSampleRate: 100, sessionOnError has no additional effect; at sessionReplaySampleRate: 100, sessionReplayOnError has no additional effect. If sessionSampleRate is 0 and sessionOnError is off, enabling only sessionReplayOnError cannot collect any sessions. To keep only error sessions and their replays, set both sample rates to 0 and enable both on-error options.Known limitations
- SPA replays do not look back across views: the replay reaches back only to the start of the view where the error occurred, up to one minute. RUM events can look back up to one minute across views.
- Leaving immediately after an error can lose history: closing or navigating away within seconds of the first error can lose part of a large upload (roughly above 64 KiB) because browsers limit data sent at page exit. Compression does not guarantee delivery. The SDK sends views and errors first; older other events and the final view update may be lost.
- Buffering replay still has a performance cost: a large, frequently changing DOM can overflow the buffer and repeatedly trigger full snapshots, adding main-thread work and shortening the available replay history. Prefer enabling only
sessionOnErroron such pages. - Manual recording has no earlier replay history: if you control recording with
startSessionReplayRecording(), explicitly setstartSessionReplayRecordingManually: true. In particular, with remote configuration enabled, the recorder may start automatically even when the initial replay sample rate is0. Do not rely on a rate of0to wait for consent. Actions before manual recording starts cannot be recovered. - Withdrawing consent does not cancel an already-triggered upload: if a session has already reported an error, withdrawing tracking consent still uploads its buffered data collected while consent was granted.
User Tracking Consent
To comply with privacy regulations like GDPR and CCPA, Flashduty RUM allows setting user tracking consent state during initialization:Example: Handling User Consent
Consent state is not synchronized or persisted across tabs. You need to provide the user’s decision during initialization or via
setTrackingConsent.View Context
You can add or modify context for the current view and its child events using these APIs:- Specify When Starting View
- Add/Modify Property
- Replace Context
Error Context
When catching errors, you can attach local context to error objects via thedd_context property:
Global Context
Global context is attached to all RUM events:Context Lifecycle
By default, global context and user context are stored in current page memory:- Not persisted after full page refresh
- Not shared between different tabs or windows
storeContextsAcrossPages option to store context in localStorage:
Micro-frontend Support
Flashduty RUM supports micro-frontend architectures by using stack trace mechanisms to identify event sources. Overrideservice and version attributes in beforeSend based on stack information:
The following events cannot be attributed to specific sources: auto-collected action events, non-XHR/Fetch resource events, view events, CORS and CSP violation events.
Integrate RUM with Distributed Tracing
Integrating RUM with distributed tracing allows you to correlate web application requests with their corresponding backend traces, enabling complete end-to-end tracing.Usage
Use theallowedTracingUrls parameter to configure API service domains for your application:
- NPM
- CDN Sync
- CDN Async
allowedTracingUrls matches full URLs and accepts the following types:
Tracing Protocol
Distributed tracing is implemented by adding corresponding header fields:traceparent:
[version]-[trace id]-[parent id]-[trace flags]version: Currently 00trace id: 128-bit trace ID, 32 characters in hexadecimalparent id: 64-bit span ID, 16 characters in hexadecimaltrace flags: Indicates sampling; 01 means sampled, 00 means not sampled
dd=s:[sampling priority];o:[origin]sampling priority: 1 means trace is sampledorigin: Always RUM, indicating collection via RUM SDK
Verification
After adding configuration, check requests sent from your application. If they correctly carry the corresponding headers, the configuration is correct.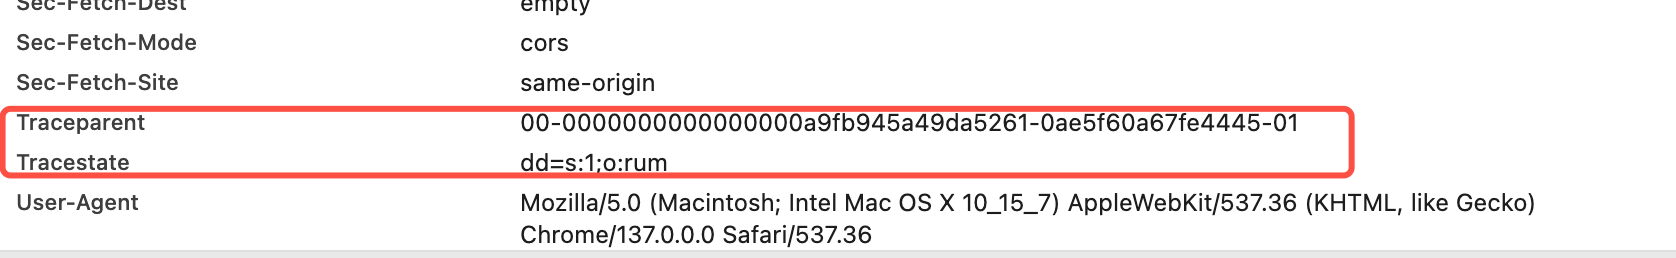
Important Notes
Related Documentation
SDK Integration Guide
Learn how to quickly integrate the RUM SDK
Data Collection
Learn about data types and attributes collected by the SDK
Troubleshooting
Solve common issues and debugging tips